


As AI-powered devices become more capable, combining different types of sensor information is becoming increasingly important. A system that can only recognize speech may understand what a person says but lack visual context. A vision-only system can identify people, objects and scenes but cannot understand spoken instructions.
A multimodal AI module combines these capabilities by processing speech, audio, images and video together. This allows intelligent devices to understand not only what users say or what is in front of a camera, but also the relationship between audio and visual information.
ShiMeta’s AIoT-M-F01 Multimodal Speech and Vision Module is designed for this type of intelligent interaction. It simultaneously receives image/video and speech/audio inputs, performs semantic fusion and understanding, and outputs voice responses, commands, alerts and text. The embedded module is compatible with RK3588, RK3576 and RK3572 platforms and is designed for intelligent terminals, robots, kiosks, automotive systems and other edge AI applications.
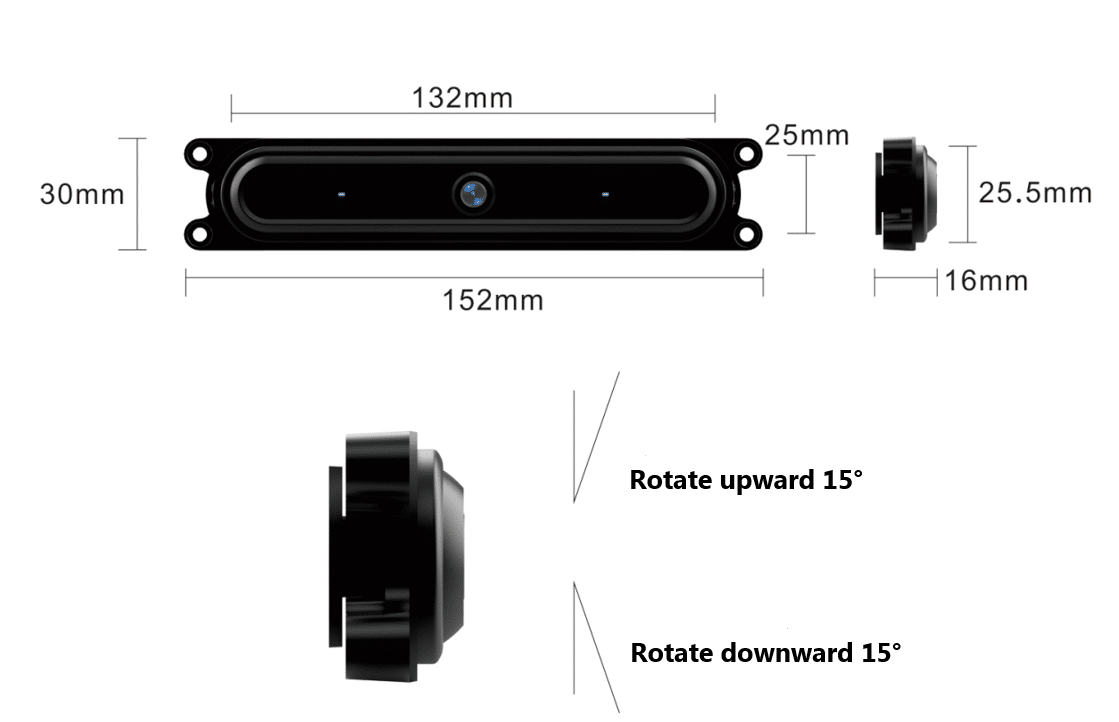
A multimodal AI module is hardware designed to process multiple types of input, such as:
Instead of processing each input independently, a multimodal system can combine information from different sources to better understand a situation.
For example, a user may point at a product and ask, “How much does this cost?” A speech-only system receives the question but may not know which product the user is referring to. A vision-only system can identify the product but cannot understand the question.
A multimodal AI system can combine the visual target and spoken instruction to create a more contextual interaction.
This is one of the key differences between traditional single-modal AI and multimodal AI interaction.
The AIoT-M-F01 is designed to combine audio and visual information in real-world environments.
The module can integrate:
This creates a unified interaction process in which an intelligent device can see, hear, understand and respond.
Instead of requiring separate speech and vision hardware, the M-F01 integrates multiple processing functions into one module, helping simplify system architecture and reduce the complexity of hardware integration.
Single-modal AI can encounter limitations in complex environments.
Speech recognition can be affected by background noise, conversations, echoes and other environmental sounds.
Vision systems may experience challenges when objects or people are difficult to see because of low-light conditions or changing environments.
By combining audio and visual information, the system can use one source of information to complement another.
For example, visual information can help verify an event when audio recognition is affected by environmental noise, while audio information can provide additional context when visual information is unclear.
This makes speech and vision AI particularly useful for interactive devices operating in dynamic environments.
One of the important applications of multimodal AI is contextual event detection.
Instead of asking only whether an object or sound exists, a multimodal system can analyze multiple signals together.
A potential emergency could be identified when the system detects that an elderly person has fallen and simultaneously recognizes a voice calling for help.
A potential equipment problem could be identified when abnormal visual conditions occur together with unusual equipment sounds.
The system can combine visual information about a customer looking at a product with a spoken question about that product.
In an intelligent vehicle cockpit, visual signs of driver fatigue can be combined with verbal expressions of drowsiness to trigger corresponding actions.
These examples demonstrate how multimodal AI can connect visual behavior and audio information to provide more contextual understanding.
For many intelligent devices, AI processing needs to happen close to where data is generated.
The AIoT-M-F01 is designed as an embedded multimodal AI module that can be integrated into existing hardware systems.
The module combines functions including:
This integrated approach can reduce the need for separate speech and vision boards and simplify cross-board integration and debugging.
For manufacturers and system integrators, this can provide a more streamlined hardware architecture for developing AI-enabled products.
Many AI applications process sensitive audio and video data.
The AIoT-M-F01 supports a local processing architecture in which raw audio and video data can remain within the device while structured results, such as events or command text, are output to the host system.
This approach is particularly relevant for applications such as:
Local processing can help reduce the need to continuously upload raw audio and video data to cloud services and supports privacy-conscious edge AI deployment.
Not every AI task needs to be processed in the same way.
The M-F01 supports a hybrid deployment approach in which simpler interactions can be handled locally, while more complex queries can be processed through cloud services when required.
This approach provides flexibility between:
Local Edge AI → Faster interaction and local processing
and
Cloud AI → Access to more complex knowledge and AI capabilities
The combination can help developers design AI systems according to different application requirements.
Developing an AI-enabled terminal from multiple independent modules can require additional hardware, algorithm licenses, integration work and cross-board testing.
The AIoT-M-F01 combines speech and vision-related functions in one module.
According to the product specification, this integrated design can help reduce:
It can also enable differentiated functions such as point-and-ask interaction, audio-visual joint alerts and real-world conversational interfaces.
AI capabilities continue to evolve after a product is deployed.
The M-F01 firmware supports OTA upgrades for multimodal models, allowing new capabilities such as object recognition and event recognition to be introduced through software and model updates.
This can help extend the usable lifecycle of AI-enabled hardware without requiring immediate hardware replacement for every new AI capability.
Multimodal speech and vision technology can be applied to many intelligent devices.
Multimodal AI can be integrated into:
These applications can combine voice interaction with visual information to create more natural human-machine interfaces.
Potential applications include:
Multimodal interaction can help retail devices understand both customer behavior and spoken requests.
The module can also be integrated into:
These applications can benefit from combining speech interaction with visual recognition.
Automotive applications include:
Multimodal perception can help connect visual information with voice-based interaction in vehicle environments.
Potential applications include:
These systems can use speech and vision capabilities to create more interactive public-facing AI terminals.
In manufacturing environments, multimodal AI can be used in:
Combining visual and audio information can provide additional context for equipment and production monitoring.
The M-F01 is also designed for:
Its embedded design makes it suitable for integration into different intelligent hardware products.
The M-F01 provides the hardware foundation for developers and manufacturers building intelligent devices that need both voice and visual perception.
| Feature | Specification |
|---|---|
| AI / Voice Chip | 6080 AI Voice Noise Reduction Computing Chip |
| Camera | Single-camera wide dynamic range |
| Camera Resolution | 5MP |
| Image Sensor | 1/2.5-inch CMOS |
| Aperture | F2.0 |
| Focal Length | 4.6 mm |
| Field of View | ≥75° |
| Microphone | 4-array directional microphone |
| Pickup Range | ≤2 m |
| Noise Reduction | AI noise reduction, noise filtering, echo cancellation and voice enhancement |
| Power Supply | 5V / 500mA |
| Maximum Power | 2.5W at full load |
| Standby Power | ≤0.05W |
| Host Connectivity | Ethernet, Wi-Fi and Bluetooth selectable through host device |
| Operating Temperature | 0°C to 50°C |
| Storage Temperature | 0°C to 60°C |
| Operating Humidity | 0–90% RH, non-condensing |
The module provides a four-microphone directional array with an effective pickup range of up to 2 meters and AI-powered noise reduction, including ambient noise filtering, echo cancellation and voice enhancement.
The next generation of intelligent devices will increasingly need to understand multiple forms of information at the same time.
A multimodal AI module can provide the hardware foundation for combining speech, audio, images and video into a more contextual AI interaction experience.
With its embedded design, local processing architecture, multimodal capabilities and compatibility with RK3588, RK3576 and RK3572 platforms, the AIoT-M-F01 is designed for AI terminal manufacturers, system integrators and developers building intelligent products across retail, robotics, education, automotive, industrial and public-service applications.
Looking for a multimodal AI module for your next product? Contact ShiMeta to discuss your hardware integration requirements.


